Usage Guidelines
Introduction
ProPilot and ProTutor rely on large language models (LLMs) to provide intelligent responses based on the information supplied. While Proteus handles much of the system context internally, understanding how these models interpret and manage input can significantly improve the consistency and accuracy of responses.
This section defines key terms and operational concepts that govern LLM behaviour, including how models handle language, manage memory, and respond to requests. These concepts underpin efficient use of EDAi assistants and inform the practical guidelines provided in the next section.
Understanding the System
Tokens
LLMs process both input and output as sequences of tokens: small units of text representing parts of words, symbols, or punctuation. The number of tokens consumed depends on both the user's prompt and the assistant's response, and each model has a fixed upper limit on the total number of tokens it can process in a single exchange.
Token usage is also the basis for cost with most providers, who typically charge per million tokens processed. This includes both input and output tokens, although some may reduce cost through caching (see below).
In Proteus, the token figure for the current session is displayed at the top right of the EDAi window. The number itself is the size of the session context, in other words how much material is being carried into each request. Hover over it for the cumulative breakdown: input tokens, output tokens, cache writes and cache hits.
See Also:
Guided Tour of the EDAi Window
As token limits are approached, the assistant may begin omitting or truncating earlier parts of the conversation to remain within bounds. This can result in loss of context or degraded performance in longer threads, particularly on models with smaller token capacities.
Stateless Operation
All language models operate in a stateless manner. They retain no memory between sessions, and each request is handled independently based on the prompt history supplied at the time. This includes the current chat thread, system context, and relevant design data such as netlists or component attributes, all of which must be resent with each prompt and response.
As conversations grow, so does the size of the prompt history, potentially increasing the token usage per interaction. However, the impact on cost is more complex. Many providers implement server-side caching, which can reduce token charges for repeated content such as the schematic or shared parts of the conversation. This means that continuing an existing chat may be more efficient than starting a new one, even if the thread is longer.
For example, the 10th question in a cached conversation might consume fewer new tokens than the 1st question in a fresh session, where the entire schematic context must be included again without prior cache benefit. Conversely, extremely long conversations can eventually reach a point where caching is less effective, or where token limits begin to drop earlier content and reduce response quality.
To help manage this, the size of the session context is shown at the top right of the EDAi window. This provides a practical, running indicator of how large the conversation has become, allowing you to balance efficiency and clarity as needed.
Bear in mind in all of this that model usage costs are generally modest, and providers charge per million tokens processed. A typical 20-question Proteus session will often consume fewer than 50,000 tokens, so micro-optimisation is largely unnecessary for most users. Check your provider's current pricing page for the rates that apply to the model you have selected.
Caching
Some AI providers (e.g. Claude, GPT) implement server-side response caching, allowing repeated prompts to return cached outputs without incurring full token costs. This can improve efficiency in longer sessions where users rephrase or refine a question.
In addition, Proteus performs smart input caching, reducing the number of tokens required to transmit recurring context, such as the schematic or netlist, on subsequent interactions. This helps keep token usage lower when working within the same project across multiple questions.
Together, these caching strategies improve cost efficiency over time. While exact behaviour varies by provider and session structure, consistent context and phrasing, combined with Proteus's optimisations, can reduce overall usage.
The cumulative figures, including the cache benefit, are in the tooltip on the token counter at the top right of the EDAi window.
Rate Limits
Most large language model (LLM) providers apply rate limits, which cap how many tokens (input plus output) can be sent or received within a short period. These limits vary by provider and are usually linked to the standing of your API account.
Entry-level accounts are generally the most constrained, and providers raise the limits as an account matures. The requirements differ from one provider to the next, but commonly involve a waiting period after sign-up and a minimum amount credited to the account. The credit is normally a deposit rather than a charge, so it remains available to spend afterwards.
This matters for ProPilot, particularly when analysing larger schematic designs. On a constrained account, complex queries involving extensive project data may approach or exceed the throughput limit, resulting in temporary delays or errors. A higher limit usually offers enough headroom for fast and fluid interaction even on larger projects.
This area is evolving rapidly: providers frequently adjust their rate caps and eligibility rules, and new models continue to improve in both efficiency and capability. Always refer to your provider's documentation for the most accurate and up-to-date information.
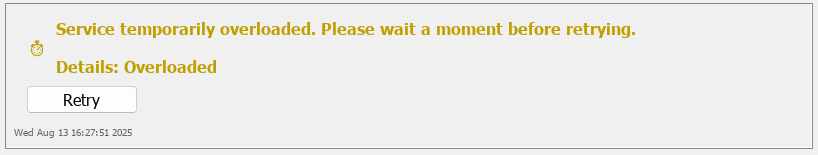
A rate-limit error returned by the provider, with a Retry button.
Prompt Context
Although most context is managed internally by Proteus, including circuit topology, simulation state and project metadata, the initial prompt remains essential in guiding model behaviour. Prompt structure defines the assistant's operational role and affects its interpretation of subsequent queries.
This concept, often referred to as the system prompt or instructional context, determines whether the assistant behaves as a calculator, analyst, code helper, or educational tutor. Accurate, unambiguous role specification at the beginning of a session improves alignment and response quality.
Practical Guidance
ProPilot is a powerful assistant, but its usefulness depends heavily on how you interact with it. While much of the technical integration and context is handled automatically by Proteus, there are still important steps you can take to ensure more accurate answers, faster responses, and lower costs. This section provides a practical framework for making the most of your assistant.
Start with a Clear, Focused Prompt
Begin each new task with a one-line instruction that explains what the model is expected to do and how it should behave. For example:
- "You are a design assistant. Review the schematic and suggest improvements."
- "You are helping me calculate timing resistor values for an RC filter with a 2kHz cutoff."
This sets the tone for the session and improves relevance of the model's replies.
Use One Chat per Task
Keep each assistant window focused on a single subject or design goal. If you change topic significantly, for example from power supply tuning to firmware bugs, start a new chat. This helps the model stay on track and keeps the prompt history efficient.
BE SPECIFIC in Your Prompts
When working with EDAi, the way you phrase a request has a big impact on the quality of the response. A vague or open-ended prompt may be interpreted as a general query, leading the assistant to summarise or assume rather than actively check your design. For example, asking "Are my ICs all powered?" invites a yes/no response and can produce a false pass, even if an issue exists.
By contrast, a directive prompt such as "Check that all my ICs are powered correctly" is explicit about the action required. This pushes EDAi into a verification mode where it inspects the schematic context, traces power pins, and confirms correct connections. In practice, being specific reduces ambiguity and ensures the assistant carries out a thorough check rather than giving a superficial confirmation.
As a rule of thumb: phrase prompts as instructions rather than questions. Use action verbs like check, verify, confirm, list, highlight to get the assistant to perform systematic analysis instead of casual commentary. This small change in prompting style can make the difference between missing a real design error and catching it before layout or manufacture. Here are a few examples.
| Bad Prompt | Good Prompt |
| Are my ICs all powered? | Check that all my ICs have valid power and ground connections. |
| Is the decoupling OK? | List every IC without a nearby decoupling capacitor and flag them. |
| Do I have pull-ups? | Check which input pins require pull-ups and confirm they are present. |
CHECK AND CHALLENGE the Response
Never assume the assistant is always right. ProPilot performs best with reasoning-based questions, and it is often helpful to interrogate the results:
- "Are you sure?"
- "That value seems high; can you explain the calculation?"
- "What assumptions are you making here?"
This not only catches mistakes but very often improves the answer on the next pass.
Critical thinking is the key to success. AI models are enormous productivity boosters and, to be honest, they make engineering a lot more fun. But always remember: you are the designer. Ask questions, talk it through, explore alternatives, explain why you disagree, and keep going until you are confident in the outcome. In our experience, two of the biggest benefits of working with ProPilot are that there are no stupid questions, and the model never gets frustrated. If you are not satisfied with a calculation or conclusion, dig deeper. You can always return to Horowitz and Hill if you need to for verification.
Watch the Token Counter
You will see the token usage displayed at the top right of the EDAi window. While costs are typically low, token limits affect performance. If answers become vague or context is lost, check the counter, because the chat may be getting too long.
Raise Your Rate Limit if Responsiveness Matters
Improving the standing of your API account with your provider raises the rate limit and can noticeably improve responsiveness on large designs. The requirements vary by provider and normally involve a waiting period after sign-up and a minimum credit on the account, which remains available for you to spend afterwards. Check your provider's account pages for the current rules.
Be Explicit When Referring to Help
If you want the model to look something up in the Proteus documentation, say so clearly:
- "In Proteus, how do I configure power rail naming?"
- "Look in the Proteus help for assembly variant management."
This steers the assistant toward the built-in help sources, including the vector database and indexed docs.
Be Specific with Parameters
When asking for formulae, component calculations, or circuit suggestions, always include known details:
- Target voltage or frequency
- Expected output behaviour
- Component types or constraints
The more context you provide, the better the assistant can tailor its suggestions.
Rephrase, Do Not Give Up
If something does not work, ask again differently. Change your phrasing, add more context, or break it into smaller questions. ProPilot is flexible and usually responds well to iterative queries. Trust yourself if in doubt: ask for justification and explanations.
Remember the System Improves Over Time
Language models are evolving rapidly. Accuracy, speed, and reliability continue to improve with every new generation and new models are coming out every few months. If you are not getting great results now, it is likely you will see better outcomes in future with the same kinds of prompts and workflows.
Remember that Model Training is Dated
AI models are trained on large datasets that are, by necessity, several months old at the time of release. This means they may not recognise brand new components, protocols, or design tools that have only recently entered the market.
Live web search closes some of that gap, but it is not available on every provider. The checkbox is greyed out on providers that do not support it:
| Provider | Live web search |
| Anthropic (Claude) | Supported |
| Open AI (ChatGPT) | Supported |
| Moonshot (Kimi) | Not currently offered. The provider's own search facility is being reworked and is unreliable in use, so Proteus does not present it to the model. |
| DeepSeek, Google (Gemini), Ollama (local), Custom | Not supported. Answers come from the model's trained knowledge only. |
Even where search is supported, the models sensibly default to answering from trained data, so you will often need to ask explicitly for a live web search to trigger one.
See Also: